H-WavJEPA
Hierarchical audio representation learning across three temporal scales.
H-WavJEPA explores learning audio representations in separate latent spaces at fine, intermediate, and coarse temporal scales. The research question is whether distinct spaces improve longer-range audio understanding while retaining useful local detail.
The repository includes a hierarchical masked-prediction prototype, EMA targets, real-WAV training, checkpoint resume, evaluation, and embedding extraction, organized with PyTorch Lightning and Hydra. It is a research implementation with no pretrained weights or established benchmark gains.
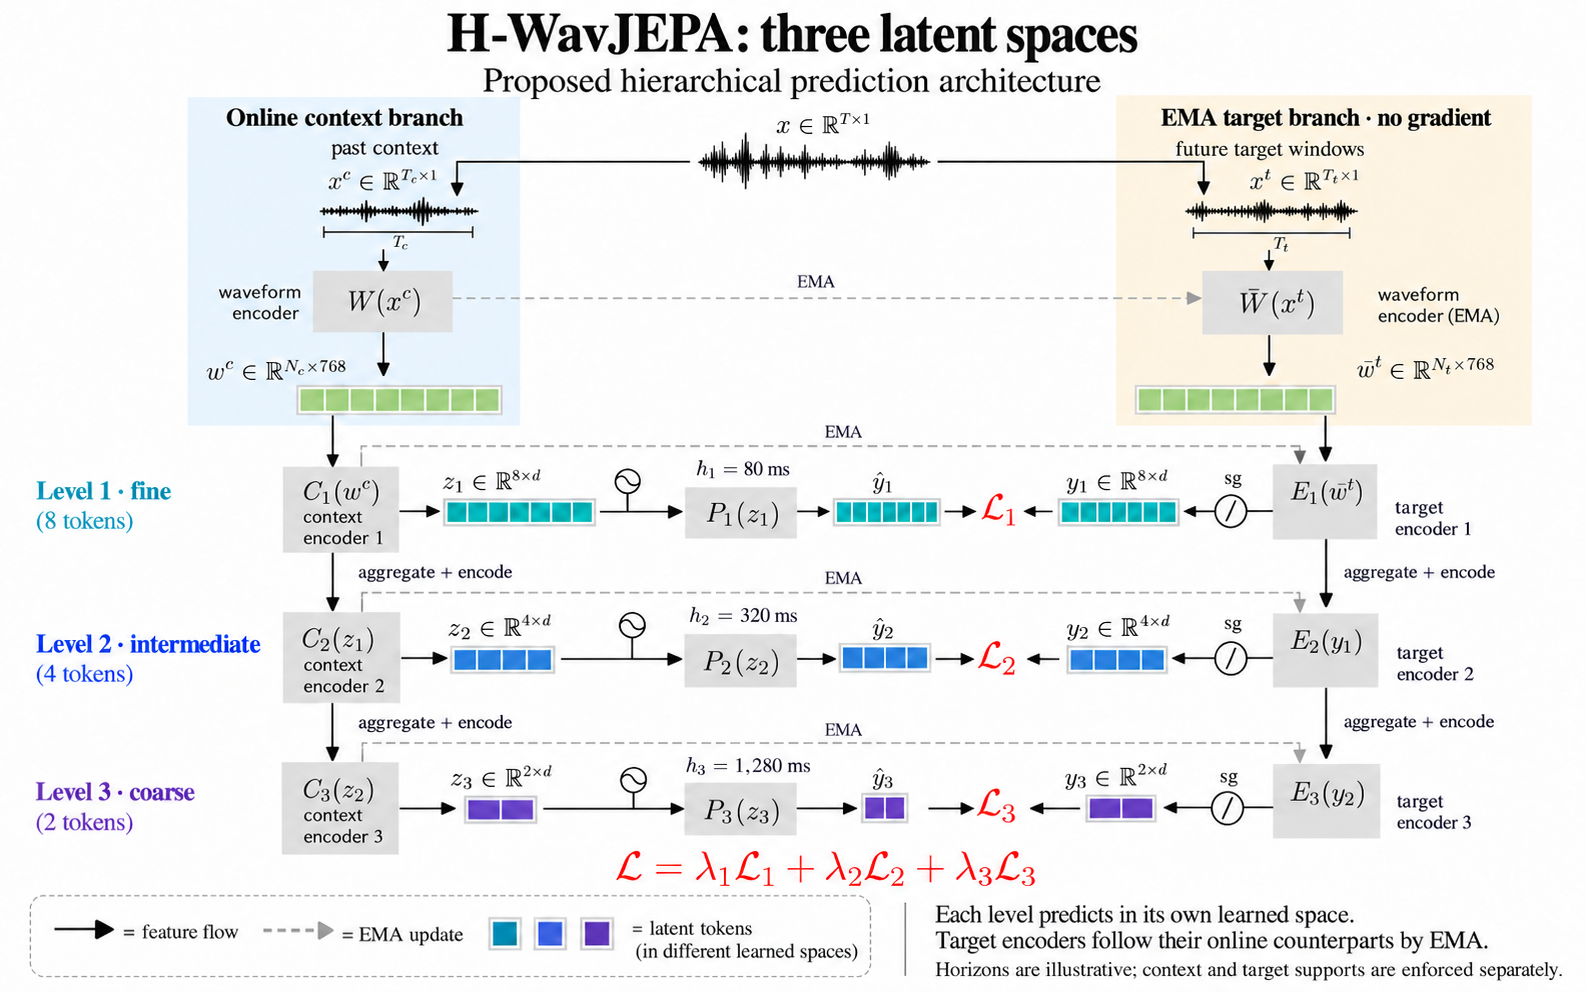
The proposed extension gives each level its own future predictor and compares the hierarchy with a shared-space model using the same horizons. The diagram describes this research direction rather than a demonstrated result.